Overview
11 stories in this issue. The first 3 are today's priorities.
Hot Model Updates
- Top · Meta's LLM-written tests caught 74 privacy SEVs before code landed
- Top · vLLM cuts a DeepSeek V4.1 Engram lookup from 54 ms to 5.1 ms on MI355X
- Top · Users report daily caps and ~40,000-character inputs on DeepSeek's free app
Global AI News
- Apple and OpenEvidence launch a study app on how people use AI for health
- Hark's Handoff² computer-use agent runs 2x faster than v1
- llama.cpp adds an x86 VNNI Q2_0 kernel, up to 3.64x faster on CPU
- OpenAI and The King's Trust launch a £1m AI skills partnership
- Paper: Gamer, a generalist vision-language-action model for long-horizon game agents
Regional and Early Signals
- Tencent releases Hy4 flash: 224B total, 12B active, free until Nov 30
- Doubao Work adds "Workbench" for 21 professional scenarios
- Hands-on: Qwen Office e-commerce edition did store setup in 3 hours, but images hallucinated
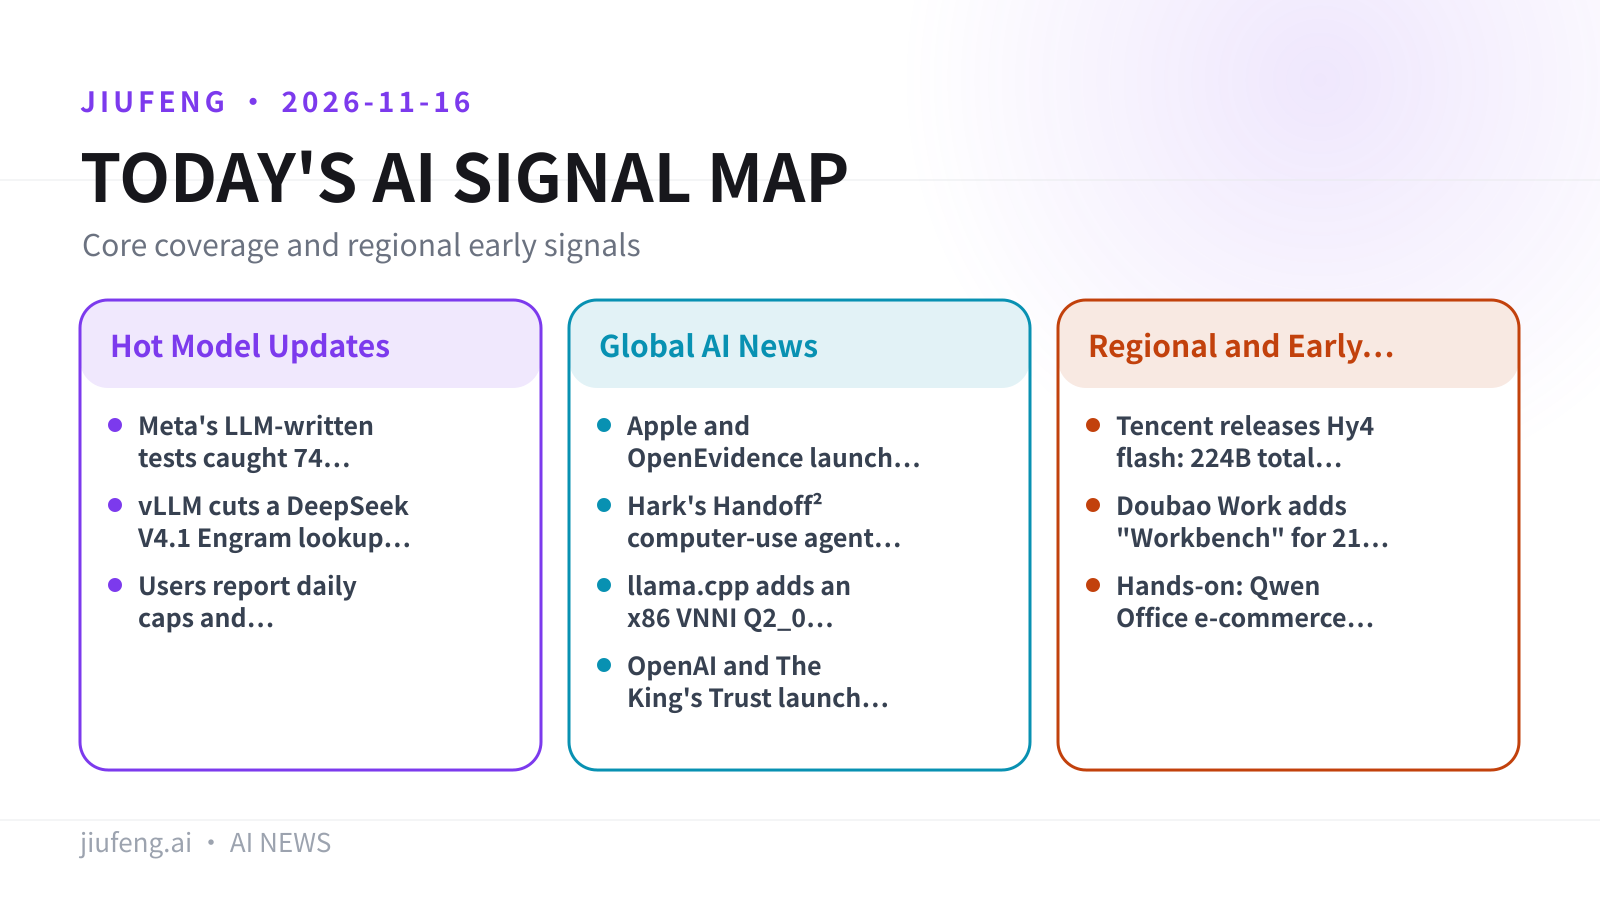
Jiufeng graphic based on the sources cited in this issue.
Hot Model Updates
01/11
Meta's LLM-written tests caught 74 privacy SEVs before code landed
Meta has put JiTTests into production: an LLM writes tests that fail when a risky diff changes behavior.
Meta has moved Catching Just-in-Time Tests (JiTTests) from a research prototype into its production infrastructure. The system uses LLMs to write executable tests that are designed to fail on risky code changes. A failing test is concrete evidence that a diff changed behavior. The method is described in the FSE 2026 paper "Just-in-Time Catching Test Generation at Meta".
- Results: 74 privacy SEVs caught at the diff stage, before landing, in H1 2026
- Scale: runs on Meta backend code with hundreds of millions of lines; the paper analyzes 22,126 generated tests
- Judge models: Llama3.3-70B, Gemini 3 Pro and Claude Sonnet 4 in the paper
- Runtime: Meta's internal infrastructure, overnight on spare capacity
Limitations: The 60% true-positive rate at full scale is reported by Meta's own engineers. JiTTests is an internal system and is not publicly available.
Source: Original source Paper on arXiv · Meta Engineering on X · MarkTechPost
02/11
vLLM cuts a DeepSeek V4.1 Engram lookup from 54 ms to 5.1 ms on MI355X
A merged vLLM change reorders how GPUs fetch rows from a host-resident table, making the largest tested lookup 10.6x faster.
Contributor Fangzhou Ai traced a DeepSeek V4.1 prefill stall on MI355X to the order in which GPUs fetched rows from a host-resident table. The merged change sorts these requests before they reach host memory.
- Test setup: 589,824-row lookup against a 94 GiB shared table on eight MI355X GPUs
- Result: 54 ms down to 5.1 ms, about 10.6x
- Activation: on ROCm, the sort path kicks in from 32,768 rows
Limitations: The 10.6x figure is the contributor's result for this single lookup step on eight MI355X GPUs.
Source: Single report RuntimeWire
03/11
Users report daily caps and ~40,000-character inputs on DeepSeek's free app
Users say DeepSeek's free app and web chat now limit usage. DeepSeek has not confirmed this.
Users report that DeepSeek's free app and web chat now cap daily use. They say inputs are cut to about 40,000 characters and older long conversations are dropped.
Limitations: All of this comes from user reports, and DeepSeek has not confirmed it.
Source: Single report Pandaily
Global AI News
04/11
Apple and OpenEvidence launch a study app on how people use AI for health
Apple is partnering with medical AI company OpenEvidence on a study app that aims to enroll up to 200,000 U.S. participants over more than 12 months.
Apple announced a new study in partnership with OpenEvidence, an AI company focused on medicine. The study app answers everyday medical questions, and the goal is to learn how clinically grounded answers can help users. Apple is inviting eligible U.S. users to take part.
- Eligibility: U.S., age 21+, iPhone 15 or later, iOS 26 or later, Apple Intelligence enabled
- Scale: up to 200,000 participants over 12+ months
Limitations: This is a research study, not an Apple health chatbot product. It is open to U.S. users only.
Source: Single report TechCrunch
05/11
Hark's Handoff² computer-use agent runs 2x faster than v1
Hark trained Handoff² with RL that penalizes latency, and it learned to batch actions.
Handoff² is the second version of the computer-use agent inside Hark Pro. Hark says the speedup comes from reinforcement learning that penalized wasted turns and latency.
| Metric | Handoff² | v1 |
|---|---|---|
| Internal alignment (%) | 93.8 | 90.3 |
- Completion: 82% on Hark's 478-task internal web benchmark
- Speed: about 2x faster end to end on average, and up to 3.8x faster for flight booking
- Runtime: Hark's cloud, with a dedicated virtual computer per request; available on web, iOS and Android
Limitations: All results come from Hark's internal benchmarks. In the same harness, its 82% browsing completion trails Claude Opus 5.5 (max) by up to 5 points. There is no local or quantized option.
Source: Single report MarkTechPost
06/11
llama.cpp adds an x86 VNNI Q2_0 kernel, up to 3.64x faster on CPU
The kernel targets AVX-VNNI or AVX-512 VNNI CPUs, and Bonsai 1.7B–27B models ran 3.0x–3.64x faster.
On November 15th, llama.cpp merged a group-64 kernel from contributor Saejin Kim-Heinert (@Michionlion). It adds an optimized implementation of ggml_vec_dot_q2_0_q8_0 for builds that target AVX-VNNI, or AVX-512 VNNI with AVX-512 VL. In the PR's CPU-only tests, Bonsai models from 1.7B to 27B ran 3.0x to 3.64x faster.
Limitations: The speedup only applies to Q2_0 quantization on these instruction sets. The tests showed a small perplexity drift, which the author attributes to compiler behavior.
Source: Single report RuntimeWire
The partnership aims to help up to 25,000 young people in the UK build practical AI skills for work.
The King's Trust and OpenAI announced a £1m partnership for young people across the UK. The goal is to help up to 25,000 of them learn to use AI in practical ways at work.
Limitations: This is a skills program, not a model or product change. Program format and timing are in the original announcement.
Source: Original source OpenAI
08/11
Paper: Gamer, a generalist vision-language-action model for long-horizon game agents
Gamer uses one training and deployment pipeline for both 2D graphical interfaces and complex 3D simulated worlds.
arXiv paper 2611.18397 was submitted on November 13th by Run Luo and 26 co-authors. Gamer is a generalist agent framework for long-horizon tasks in complex interactive environments. Its end-to-end architecture combines perception, memory management and multi-step reasoning. One shared training and deployment pipeline handles both conventional 2D GUIs and 3D simulated worlds.
Limitations: The abstract gives no benchmark scores, parameter counts or weight license. Capability claims need to be checked against the full paper and any released models.
Source: Original source arXiv
Jiufeng graphic based on the sources cited in this issue.
Regional and Early Signals
Hy4 flash is a lower-cost version of Hy4, and Tencent's figures put its per-task cost at 1/20 of Hy4. (Chinese-language source)
According to ifanr (APPSO), Tencent officially released Hy4 flash on November 16th. It is meant to bring Hy4's agent and long-horizon task abilities to high-frequency use at lower cost.
- Parameters: 224B total, 12B active
- Capabilities: multimodal, 1M context
- Pricing: ¥0.5 per million input tokens and ¥2 per million output tokens, roughly one-tenth of Hy4
- WorkIndex per-task cost: 1/13 of Hy4 preview, 1/20 of Hy4, and 1/8 of DeepSeek-V4.1-Flash-1017 (max tier, peak pricing)
- Availability: selectable in WorkBuddy, with a free daily quota from Nov 16 to Nov 30
Limitations: The cost comparisons come from Tencent's figures and a media preview test, not an independent benchmark. The report does not say whether weights will be released. The only source is in Chinese.
Source: Single report ifanr (Chinese-language source)
10/11
Doubao Work adds "Workbench" for 21 professional scenarios
Workbenches for fields such as finance, medicine and education come with preset skills and plugins, and the finance one connects to Wind and Tonghuashun data. (Chinese-language source)
Doubao Work has launched "Workbench", starting with 21 professional scenarios. The finance research workbench connects to data plugins from Wind, Tonghuashun and Guotai Haitong, which users can call after they authorize their terminal accounts. The teacher workbench has an official partnership with Zxxk for teaching resources and similar-question search. Users can also build and share custom workbenches. The feature is live in the desktop versions of Doubao Work and Doubao.
Limitations: The "industry first" label is the company's own claim. The feature is desktop-only for now. The only source is in Chinese.
Source: Single report Leiphone (Chinese-language source)
11/11
Hands-on: Qwen Office e-commerce edition did store setup in 3 hours, but images hallucinated
A tester with no e-commerce experience used Qwen Office to get through seven store-setup steps. Model output took about 30 minutes and cost about ¥47 in tokens. (Chinese-language source)
A hands-on test split store setup into seven steps: market research, pricing, store naming, product assets, inventory, listing checklist and customer-service scripts. The whole process took about 3 hours, including time spent checking and editing the AI's output.
| Step | Qwen Office | Manual (newcomer) |
|---|---|---|
| Market research | 8 min 48 s | 1–2 days |
| Product images | 19 images in 15 min, ~¥33.75 | 3–5 days outsourced, ~¥1,000s |
| Decor/stock/listing/scripts | under 2 min each | half to one day each |
Limitations: According to the source, the market research output was basic, and image generation had the most problems, including hallucinated content. Core steps still needed human review. This was a single test by one outlet. The only source is in Chinese.
Source: Single report TMTPost (Chinese-language source)
This digest is compiled by AI from the sources linked in each item and published after automated fact-checking, without article-by-article human review before publication. If anything differs from the original, the original source prevails. How this digest is made, or report an error: About this digest
OpenAI’s latest image model, strongest at legible text and dense layouts — posters, packaging, dashboards. Generate in your browser. 5 free credits on sign-up, no credit card.
Open GPT Image 2.5