Overview
9 stories in this issue. The first 3 are today's priorities.
Hot model updates
- Top · Kolibri releases 78GB FP8 open weights
- Top · Mac and iPhone split Qwen prefill work
- Top · Strata lists local Qwen3.8-Flash-Next options
- OpenAI safety author leaves the company
Global AI news
- Muse Gadgets opens ESP32 firmware and Linux SDK
- Capcom plans AI development workflows
- Cotool packages security investigations as agents
- RuntimeWire reports 986 AI newsroom stories
Regional and early signals
- Vertical AI emerges in private tech accounts
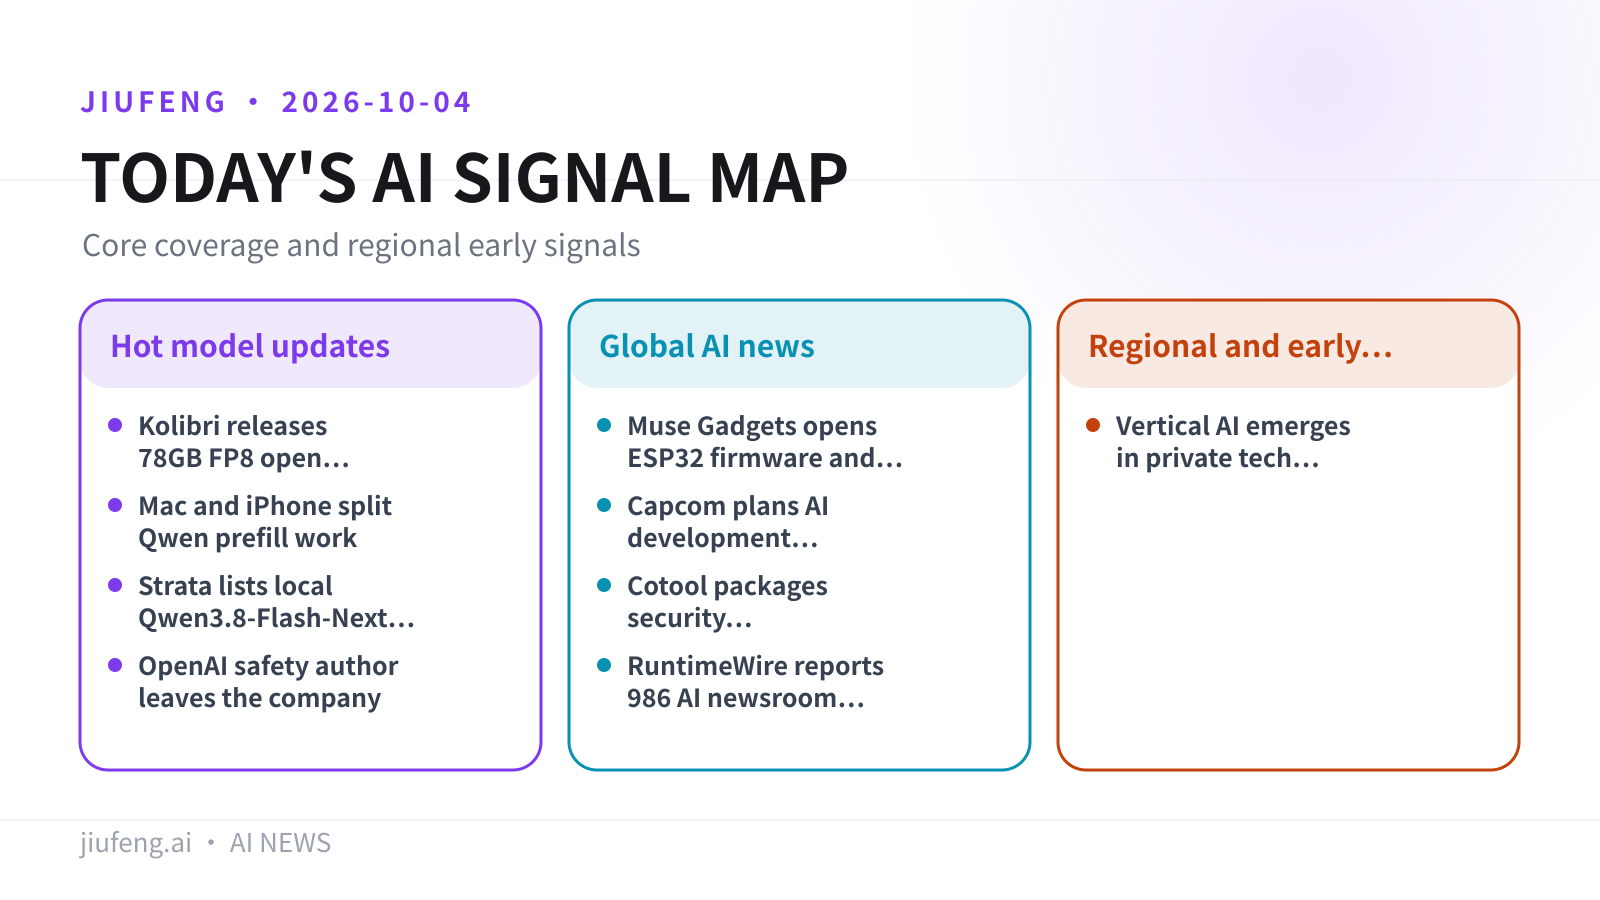
Jiufeng graphic based on the sources cited in this issue.
Hot model updates
01/09
Kolibri releases 78GB FP8 open weights
Aleph Alpha released Kolibri, a German-English MoE model with Apache 2.0 weights.
Aleph Alpha released Kolibri on October 3, and its weights are available through Hugging Face. The model is a German-English mixture-of-experts model.
- Total parameters: 78.1 billion
- Active parameters per token: 3.46 billion
- Weight footprint: about 78GB FP8
- License: Apache 2.0
Limitations: The model card specifies a minimum of two A100 80GB GPUs, creating a substantial local deployment requirement.
Image source: huggingface; mirrored on Jiufeng R2.
Source: RuntimeWire · Hugging Face model card
02/09
Mac and iPhone split Qwen prefill work
A user connected a MacBook Pro to an iPhone 17 Pro Max and reported up to 44% faster Qwen3.8-27B prefill.
The setup assigns layers 1 through 40 to an M4 Pro MacBook Pro and layers 41 through 64 to the iPhone’s A19 Pro GPU. At 16K context, prefill rose from 109 to 157 tokens per second; at 8K, it rose from 132 to 177.
| Context length | Mac only (token/s) | With iPhone (token/s) | Gain |
|---|---|---|---|
| 8K | 132 | 177 | 35% |
| 16K | 109 | 157 | 44% |
| 32K | 101 | 130 | 29% |
Limitations: This is a user-built open-source setup reported through a Chinese-language source. Below 64K context, generation remains on the Mac and is not accelerated by the phone.
Source: IT之家
03/09
Strata lists local Qwen3.8-Flash-Next options
Strata documents multiple compressed Qwen3.8-Flash-Next variants selected by available memory.
Its documentation recommends Coder for 32GB RAM, IQ2_XS or Q2_0 for 48GB, and several variants for 64GB or more. The Coder version retains 256 of 512 experts selected on code data, and the documentation says it is weaker outside coding and in languages other than English.
- 32GB RAM: Coder
- 48GB RAM: IQ2_XS or Q2_0
- 64GB RAM: IQ2_XS, IQ3_XXS, or IQ3_S
- Coder experts: 256 of 512
Limitations: The candidate’s Claude comparison is a community lead; the provided project documentation contains no task-by-task scores, so it does not establish a benchmark ranking.
Source: Strata model documentation · Qwen3.8-Flash-Next
04/09
OpenAI safety author leaves the company
David Robinson, who wrote OpenAI model safety reports, resigned and publicly criticized industry culture.
The Verge reports that Robinson left OpenAI this week and wrote an editorial for The Atlantic. He argued that the issue extends beyond adding rules or regulation and criticized Silicon Valley’s “extreme confidence” around AI.
Limitations: The account is a former employee’s public criticism, not an official OpenAI description of a specific model-release process.
Source: The Verge
Global AI news
05/09
Muse Gadgets opens ESP32 firmware and Linux SDK
Meta released Apache 2.0-licensed Muse Gadgets for DIY hardware connected to its Muse AI agent.
The project includes ESP32 firmware and a Linux SDK for connecting homemade devices to Muse. Meta also built Muse Home Link, a USB-C device for controlling TVs, speakers, and other HTTPS-connected home devices; the report says 5,000 units were produced.
- License: Apache 2.0
- Hardware: ESP32
- Initial production: 5,000 units
- Connection path: Linux SDK and HTTPS
Limitations: Home Link is expected to ship free to Muse subscribers while supplies last, and the project does not define the full scope of third-party hardware compatibility.
Source: The Decoder · Muse Gadget SDK
06/09
Capcom plans AI development workflows
Capcom said it plans to integrate AI technology into development workflows for its RE Engine work.
At Capcom Open Conference RE: 2026, programmer Satoshi Ishida discussed the REX Project and the next generation of RE Engine. He described the time required for work on large games and presented AI integration as part of the development workflow.
Limitations: The report does not identify a model, launch date, supported production stages, or measured productivity results.
Source: The Verge
07/09
Cotool packages security investigations as agents
Cotool offers configurable AI agents for security teams to reuse investigation and response workflows.
RuntimeWire reports that the startup was founded by former Material Security operators and focuses on collecting context across security tools. Cotool says it is in production at Ramp and EliseAI, and it raised a $7.4 million seed round led by a16z in March 2026.
Limitations: Customer deployment and time-saving claims are company-reported; the report says clearer measurement and independent validation are still needed.
Source: RuntimeWire
08/09
RuntimeWire reports 986 AI newsroom stories
RuntimeWire says its AI-powered newsroom published 986 stories in 30 days with a 36-minute median turnaround.
The company says it processed 957 million tokens, cited 6.1 sources per article on average, and monitored 77 feeds: 49 RSS feeds, 21 company newsrooms, and seven X accounts. It also says a curator screened 886 stories in the 24 hours before the report.
| Metric | Reported figure |
|---|---|
| 30-day output | 986 stories |
| Median turnaround | 36 minutes |
| Average cited sources | 6.1 per story |
| Monitored feeds | 77 |
Limitations: These figures are founder-reported production metrics rather than independently audited newsroom measures; traffic and revenue figures were not yet available.
Source: RuntimeWire
Regional and early signals
09/09
Vertical AI emerges in private tech accounts
A conference roundup identifies proprietary data, industry workflows, and purpose-built hardware as vertical AI differentiators.
SiliconANGLE’s report on the Bank of America Private Tech Trailblazers Conference covers companies working in restaurants, construction, healthcare, cross-border payments, and defense. It frames specialization around proprietary data, vertical integration, trust, and capital needed to operate at scale.
Limitations: This is a conference and industry roundup, not a standardized product evaluation or a set of comparable company operating metrics.
Source: SiliconANGLE
Write a prompt in your browser and get an image — 1K, 2K or 4K output, up to 15 reference images. 50 free generations on sign-up, no credit card.
Generate free

